Less re-keying. Fewer errors. Faster client onboarding.
Every client, carrier and partner sends data differently, and someone on your team makes it fit. We build the pipelines, integrations and automation that take manifests, order files and status updates from wherever they arrive to wherever they need to be, checked on the way.
Built for
- 3PL operators
- Freight forwarders
- Warehouse operators
- Distribution businesses
- Logistics companies
The manual work between your systems.
Logistics runs on data from other people’s systems. The more clients and carriers you work with, the more formats, portals and spreadsheets someone has to reconcile by hand.
Manual manifest processing
Manifests arrive by email or portal download. Someone opens each one, copies the shipments into the dispatch or carrier system, and checks the totals by eye.
Inconsistent CSV formats
Every client and carrier sends a different layout: different column names, delimiters, date formats and units. Each new client adds another one.
Repetitive data entry
The same consignee, reference and weight are typed into the WMS, the TMS, the carrier portal and the client’s spreadsheet.
Duplicate shipment records
A file is sent twice, or a corrected version follows the original. Shipments get booked twice, or the wrong version wins.
Data validation errors
Missing postcodes, impossible weights, unknown service codes. They are found at dispatch, or by the carrier, instead of when the file arrives.
Disconnected dispatch systems
Dispatch, warehouse and carrier systems each hold part of the picture, and status updates only reach clients when someone sends them.
Every file through the same careful process.
Instead of a different manual routine for each client and carrier, every file goes through one pipeline. The differences between sources are handled once, in configuration, not every day by a person.
Stage 1
File ingestion
Files are collected from where they already arrive, such as email attachments, SFTP folders or portal exports, and logged with their source and time.
Stage 2
Extraction & normalization
Each source’s layout is mapped once to a standard shipment format. Column names, dates, units and codes are made consistent.
Stage 3
Validation & deduplication
Every record is checked against agreed rules and compared with shipments already received, so resent files don’t create duplicates.
Stage 4
Structured output
Clean shipments come out in one consistent structure, whatever the source looked like.
Stage 5
Database or system integration
Records are loaded into your database, or sent to the WMS, TMS or dispatch system that needs them.
Stage 6
Error reporting
Rejected records are reported with the reason, to your team or back to the client, so they can be fixed and resent.
Three layouts in. One shipment format out.
Two clients and a carrier send the same kind of information with different column names, delimiters and units. Here is how that becomes one clean, consistent record.
1. File ingestion
Client AEmail attachment
Consignee,Post Code,Wt (kg),RefClient BSFTP folder
ship_to_name;zip;weight_lbs;order_noCarrier exportPortal download
RECIPIENT|POSTCODE|KG|AWB
2. Extraction & normalization
Example of how differently named columns from three sources map to one standard field Standard field Client A Client B Carrier recipient_name Consignee ship_to_name RECIPIENT postcode Post Code zip POSTCODE weight_kg Wt (kg) weight_lbs → kg KG reference Ref order_no AWB Each layout is mapped once. A new client means a new mapping, not a new manual process.
03
Validate & deduplicate
Required fields, postcode format and weight limits checked. Shipments already received are skipped.
04
Structured output
One standard shipment record, whatever the source looked like.
05
Integrate
Loaded into your database, or sent to the WMS, TMS or dispatch system that needs it.
06
Report errors
Rejected rows go to the right person, or back to the client, with the reason.
The same approach, already running.
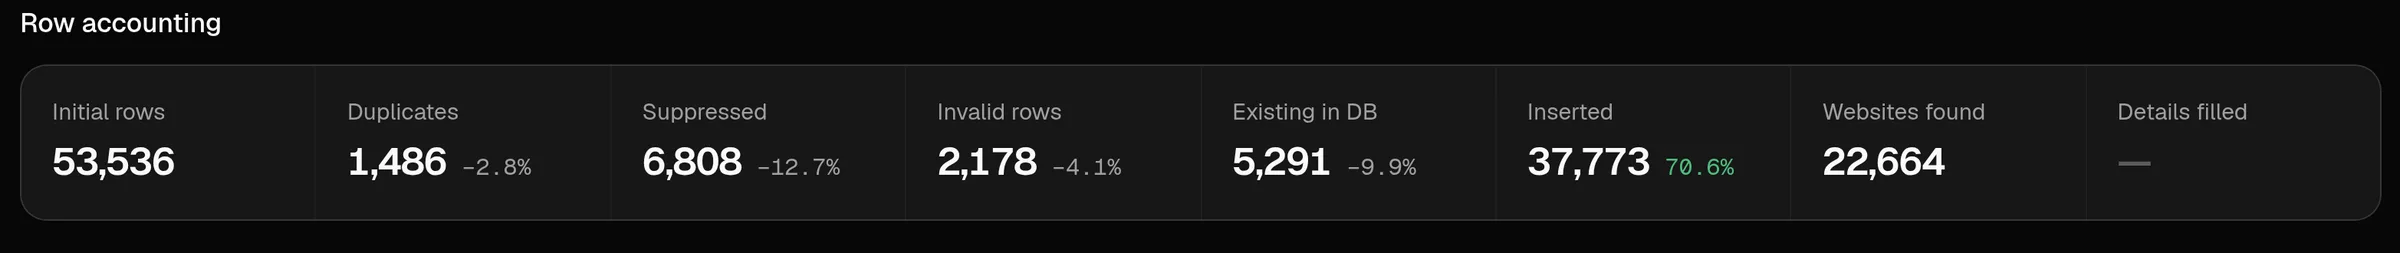
DropFilter is a pipeline we built for a client’s team. Every daily CSV upload goes through staged checks (deduplication, validation, a lookup against the production database) and only new, valid rows are loaded into PostgreSQL, in one all-or-nothing transaction, with every removed row kept with its reason.
To be clear
DropFilter processes contact data, not shipments, and it isn’t a product you can buy or connect to your WMS. It shows how we build: the same stages, row accounting and audit trail are what a manifest pipeline needs.
What we build for logistics teams.
Data Pipelines & Processing
The core of manifest and client-file handling: ingestion, normalization, validation, deduplication and delivery.
View serviceCustom Software Integrations
Connections to your WMS, TMS, dispatch and carrier systems, and to client systems during onboarding.
View serviceOperational Automation
Error reports, client status updates, daily stock and shipment reports, and billing data preparation.
View serviceBy business type
- 3PL operators
- Client onboarding, multi-client order and stock feeds, per-client billing data and reporting.
- Freight forwarders
- Booking and shipment data from partners and carriers, status updates and invoice checking.
- Warehouse operators
- Inbound ASN and manifest processing, WMS integration and stock reconciliation.
- Distribution businesses
- Order intake from customers and reps, ERP and WMS sync, inventory accuracy across sites.
- Logistics companies
- Dispatch data from multiple sources, proof-of-delivery and status updates back to customers.
Switched over one source at a time.
Your operation can’t stop while a new system goes in. So we start from your real files, run in parallel, and move clients and carriers across gradually.
- Step 1:
Collect samples
We gather real files from each client or carrier involved, including the messy ones.
- Step 2:
Agree the rules
Field mappings and validation rules are agreed per source and written into the scope.
- Step 3:
Build & run in parallel
The pipeline runs alongside your current process so results can be compared before switching.
- Step 4:
Go live source by source
Clients and carriers are moved over one at a time, so nothing changes all at once.
- Step 5:
Monitor & extend
Errors are reported as they happen. New clients are added with a new mapping.
Common questions.
Can you handle a different file format for every client?
Yes. That is the main problem this kind of pipeline solves. Each client’s layout is mapped once to a standard format and tested against samples of their real files. Adding a client later means adding a mapping, not a new manual process.
Our manifests sometimes arrive as PDFs. Can you process them?
Sometimes. PDFs with a consistent, machine-readable layout can often be processed reliably; scanned or inconsistent documents are much harder. We test your actual PDFs during discovery and only include them in the scope once we know they can be handled accurately.
Can we use DropFilter for our manifests?
Not directly. DropFilter is a pipeline we built for a client, and it processes contact data, not shipments. It isn’t a product you can buy, and it doesn’t connect to WMS, TMS or carrier platforms. We would build a pipeline for your files using the same approach: staged checks, rejected rows kept with reasons, and an all-or-nothing load.
Do we need to replace our WMS, TMS or dispatch system?
No. We connect to the systems you already use, through their API, database or file exports, after confirming what each one supports.
What happens to records that fail validation?
They are held back with the reason they failed and reported to the right person, or back to the client. Nothing is silently dropped, and corrected records can be resent without creating duplicates.
Where does our data live, and who owns it?
In the database and systems agreed in the scope. You own the code, the data and the accounts it runs on.
How do projects usually start?
With one flow: one client’s files, one carrier’s manifests or one recurring manual task. It is scoped in writing, built, run alongside the current process, and extended once it is working.
Which part of your operation is still manual?
Send us a description of the process, or a sample file with the sensitive data removed. An engineer will reply with an honest view of what’s worth building, and what isn’t.
- Reply from an engineer
- Written scope before any build
- You own what we build